


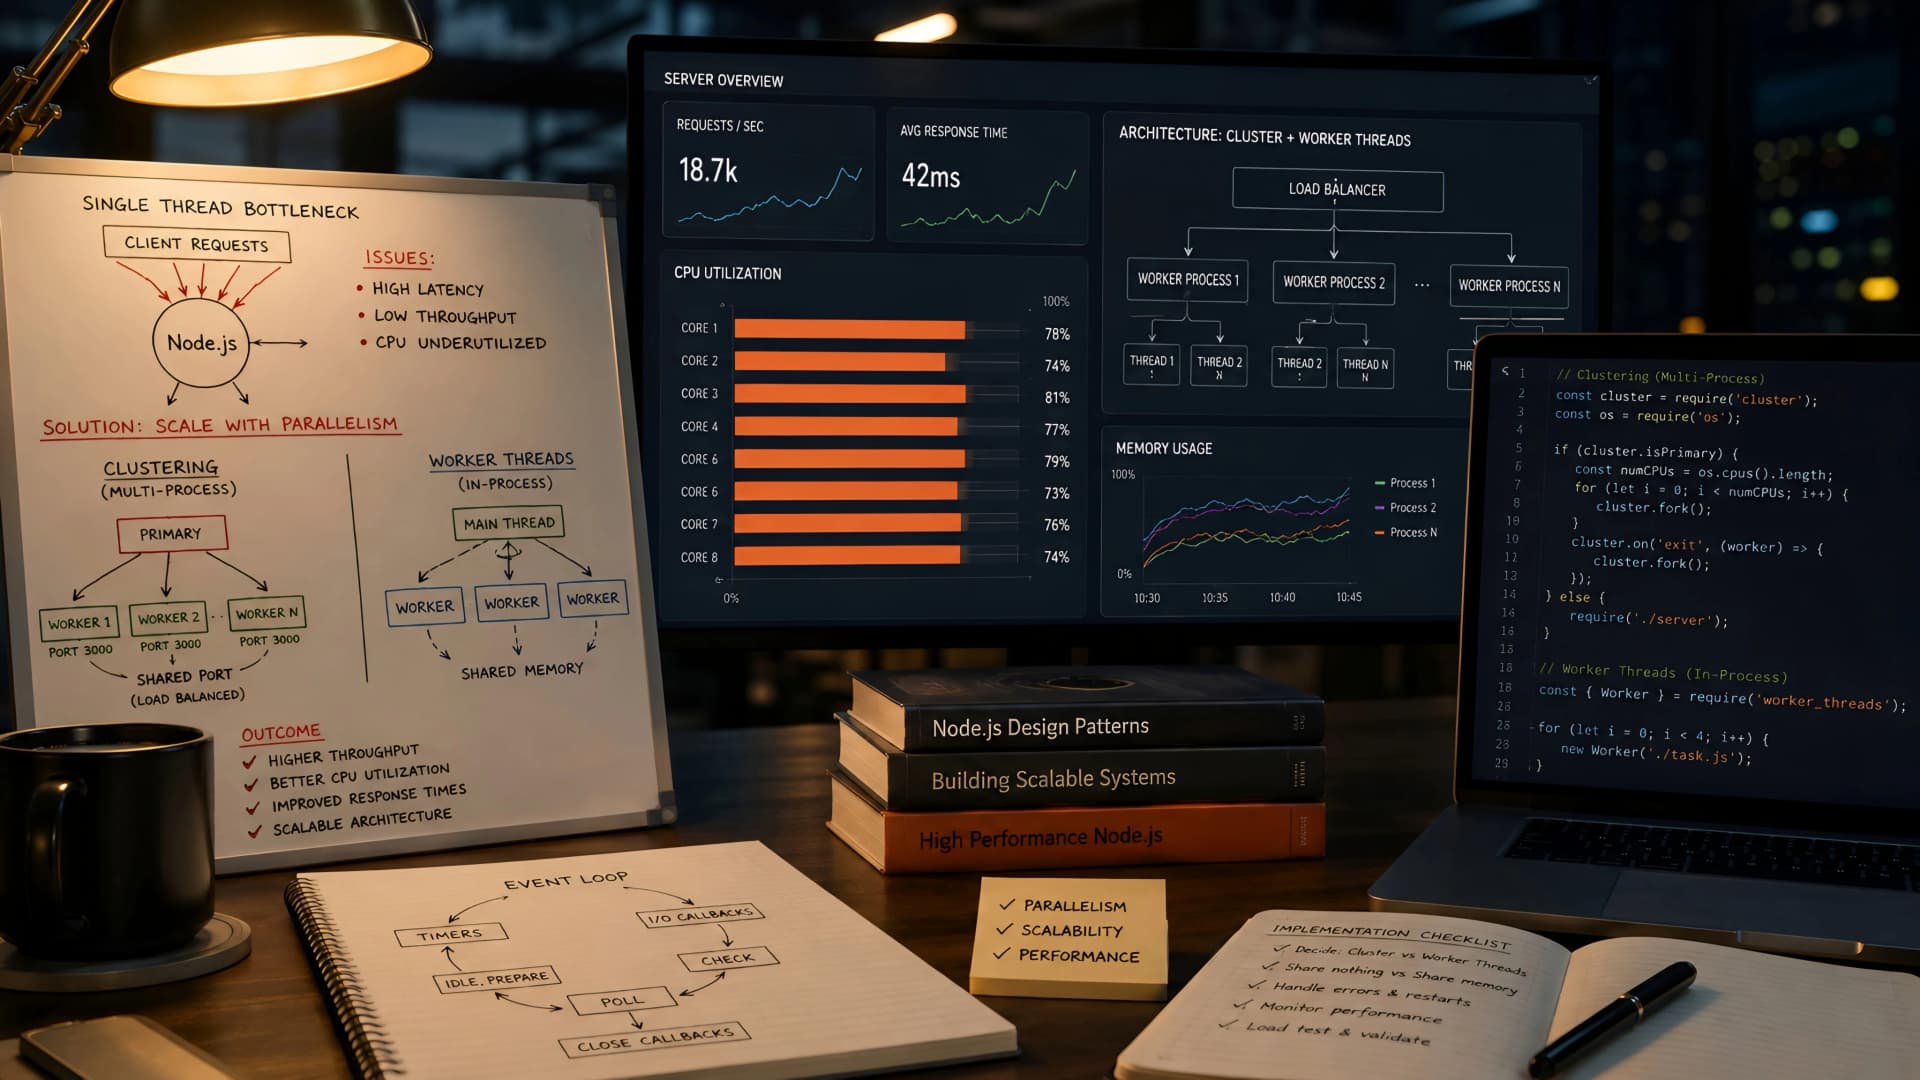
Node.js revolutionized backend development with its non-blocking I/O model, making it incredibly efficient for many web applications. However, its single-threaded nature often raises questions when facing CPU-intensive tasks.
Processing large datasets, complex image manipulations, or heavy computations can quickly bottleneck a Node.js process, leaving multiple CPU cores idle. This is a common pain point we address when designing robust full-stack web applications.
The Single-Threaded Challenge in Node.js
By default, a Node.js application runs on a single thread within a single process. This architecture is fantastic for I/O-bound operations, where the application spends most of its time waiting for external resources like databases or APIs.
The event loop efficiently handles concurrent connections without creating new threads for each. However, if a single request triggers a CPU-heavy operation, it can block the entire event loop, slowing down or even freezing all other incoming requests.
At Muhyo Tech, we frequently encounter scenarios where clients need to perform heavy calculations or data transformations. Relying solely on the single-threaded model for these tasks inevitably leads to performance ceilings and user frustration.
Node.js Clustering: Distributing the Load
Node.js clustering is a built-in module designed to address this limitation by allowing a single Node.js application to run across multiple CPU cores. It works by creating a 'master' process that forks 'worker' processes.
Each worker process is an independent instance of your application, running on its own thread and handling incoming requests. The master process can then distribute these requests among the workers using a round-robin approach.
How Clustering Works in Practice
Imagine you have a 4-core server. With clustering, you can launch four worker processes, each utilizing one core. When a user makes a request, the master process directs it to an available worker.
This effectively multiplies your application's capacity to handle concurrent requests and CPU-bound operations. It also adds a layer of resilience: if one worker crashes, the others continue running, and the master can even respawn the failed worker.
const cluster = require('cluster');
const http = require('http');
const numCPUs = require('os').cpus().length;

if (cluster.isMaster) {
  console.log(`Master ${process.pid} is running`);

  for (let i = 0; i < numCPUs; i++) {
    cluster.fork();
  }

  cluster.on('exit', (worker, code, signal) => {
    console.log(`Worker ${worker.process.pid} died`);
    cluster.fork(); // Respawn a new worker
  });
} else {
  // Workers can share any TCP connection
  // In this case it is an HTTP server
  http.createServer((req, res) => {
    // Simulate a CPU-intensive task
    if (req.url === '/heavy') {
      let sum = 0;
      for (let i = 0; i < 1e9; i++) {
        sum += i;
      }
      res.writeHead(200);
      res.end(`Hello from worker ${process.pid}! Sum: ${sum}\n`);
    } else {
      res.writeHead(200);
      res.end(`Hello from worker ${process.pid}!\n`);
    }
  }).listen(8000);

  console.log(`Worker ${process.pid} started`);
}
Worker Threads: Fine-Grained Concurrency for CPU Tasks
While clustering handles concurrent requests at the process level, Node.js worker threads (introduced in Node.js 10.5.0 and stable since 12.x) offer a more granular solution. They allow you to run CPU-intensive JavaScript code in parallel within the same Node.js process.
Unlike cluster workers, which are full process copies, worker threads share the same memory space (though messages are passed via cloning, not shared memory directly for primitives). This makes them ideal for offloading specific, isolated computational tasks without blocking the main event loop.
Implementing Worker Threads
You define a separate JavaScript file for your worker logic. The main thread then spawns a worker, sends data to it, and listens for results. This pattern ensures the main thread remains free to handle incoming requests and I/O operations.
When we optimize website speed for complex applications, isolating heavy tasks with worker threads is a key strategy. It prevents a single complex operation from degrading the entire user experience.
// main.js
const { Worker, isMainThread, parentPort, workerData } = require('worker_threads');

if (isMainThread) {
  console.log('Main thread started');
  const worker = new Worker(__filename, {
    workerData: { num: 40 }
  });

  worker.on('message', (result) => {
    console.log(`Fibonacci result: ${result}`);
  });

  worker.on('error', (err) => {
    console.error(err);
  });

  worker.on('exit', (code) => {
    if (code !== 0) console.error(`Worker stopped with exit code ${code}`);
  });
} else {
  // worker.js logic (runs in the worker thread)
  function calculateFibonacci(n) {
    if (n <= 1) return n;
    return calculateFibonacci(n - 1) + calculateFibonacci(n - 2);
  }

  const result = calculateFibonacci(workerData.num);
  parentPort.postMessage(result);
}
Clustering vs. Worker Threads: Choosing the Right Tool
The choice between clustering and worker threads depends on the specific problem you're trying to solve. They are not mutually exclusive and can even be used together.
- Clustering is best for horizontal scaling of your entire application, distributing incoming HTTP requests across multiple CPU cores. It's about maximizing throughput for many concurrent users.
- Worker Threads are ideal for vertical scaling of specific, CPU-bound tasks within a single application instance. They keep the main event loop free for I/O and other non-blocking operations.
For example, a web server might use clustering to handle many users concurrently, and within each worker, use worker threads to offload image processing tasks triggered by individual requests.
Engineering Considerations and Trade-offs
While powerful, both clustering and worker threads introduce their own set of complexities. Shared state management becomes a concern with clustering, as each worker has its own memory. You'll need external stores like Redis for session data or shared caches.
Worker threads, while sharing some memory, communicate via message passing, which adds overhead. Debugging can also become more intricate when dealing with multiple processes or threads.
Our approach at Muhyo Tech emphasizes understanding these trade-offs early in the MERN stack web development process. We design architectures that leverage these tools strategically, ensuring maintainability and predictable performance rather than over-engineering.
Monitoring is crucial. You'll need tools to track the health and performance of individual cluster workers and to ensure worker threads are not introducing new bottlenecks. Properly configured monitoring helps identify when to scale up or out.
Maximizing Business Value
Implementing clustering and worker threads directly translates to tangible business benefits. Maximized hardware utilization means you get more performance out of your existing infrastructure, potentially delaying expensive hardware upgrades.
Increased application throughput allows your application to handle more users and more intensive operations without degradation. This leads to a smoother user experience, higher customer satisfaction, and better conversion rates.
Enhanced resilience against single-point failures in a clustered setup means your application remains available even if one worker crashes. This improves reliability and reduces potential downtime, protecting your business reputation and revenue.
Conclusion
Node.js, despite its single-threaded core, offers robust mechanisms for scaling CPU-bound applications. By strategically applying clustering for process-level distribution and worker threads for granular task concurrency, engineers can unlock the full potential of multi-core processors.
Understanding when and how to deploy these tools is fundamental to building high-performance, resilient web applications. It's a key part of our engineering philosophy at Muhyo Tech: crafting solutions that are not just functional, but also robust, scalable, and built for the long term.