


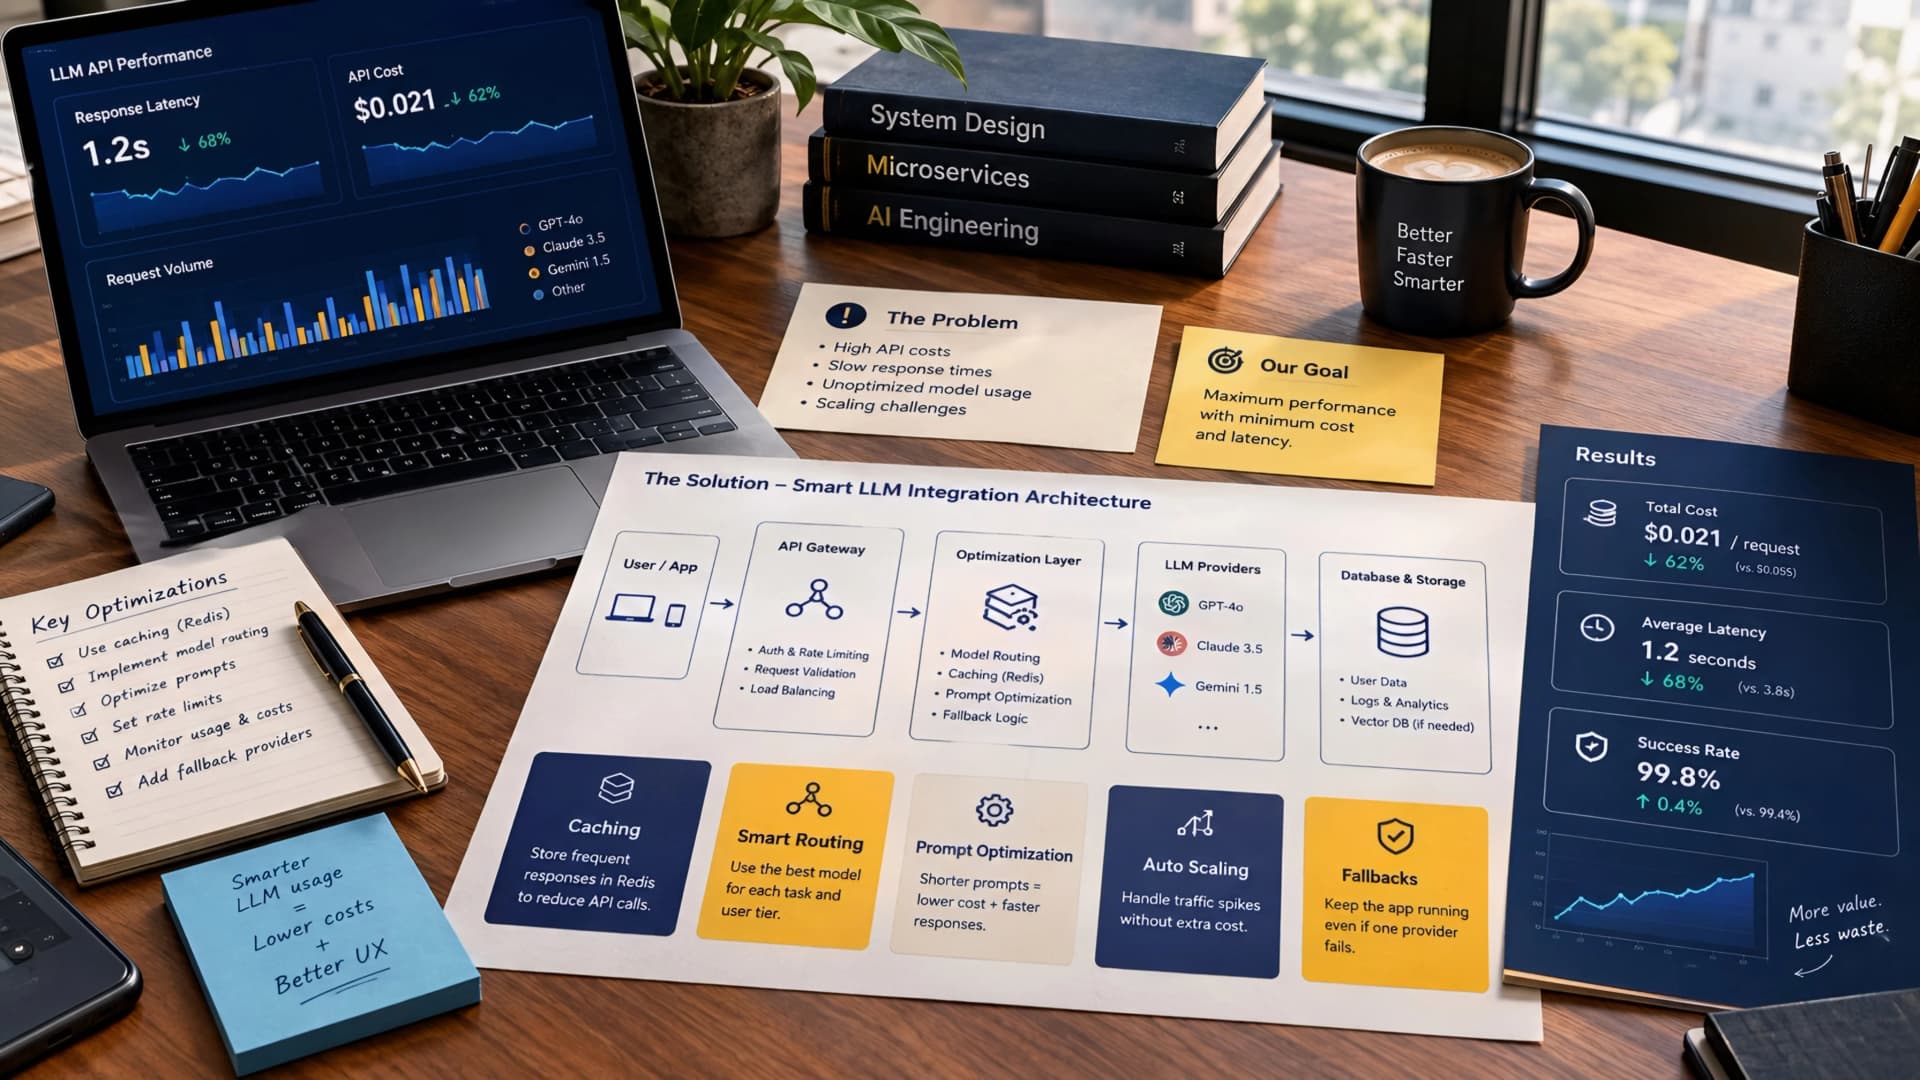
Integrating Large Language Models (LLMs) into Micro-SaaS products presents a dual challenge: managing the operational costs of API calls and ensuring a responsive user experience. Slow responses or unexpectedly high bills can quickly erode user trust and product viability.
Many founders start with direct API calls, which is fine for initial prototypes. However, scaling an AI feature without proper architectural considerations often leads to significant friction down the line.
The Core Problem: Cost and Latency at Scale
Every API call to a sophisticated LLM incurs a cost, usually per token, and introduces network latency. For a growing Micro-SaaS with increasing user interactions, these small costs and delays quickly compound.
Users expect instant feedback, and even a few extra seconds of waiting can feel like an eternity, especially for interactive AI features. This directly impacts user retention and satisfaction, making thoughtful optimization crucial.
Strategic Caching: Your First Line of Defense
The most straightforward way to reduce both cost and latency is effective caching. If an identical LLM prompt is sent multiple times, why pay for and wait for the same response repeatedly?
We implement a robust caching layer for common or predictable LLM requests. This means storing the output of previous API calls and serving them directly if the input parameters match, bypassing the external API entirely.
Implementing Smart Caching
A simple in-memory cache might suffice for low-volume applications, but for production systems, a distributed cache like Redis or Memcached is often necessary. The key is to design cache keys that accurately reflect the input, ensuring data integrity.
Consider cache invalidation strategies carefully. If the underlying data or context for an LLM prompt changes, the cached response becomes stale. Implementing time-to-live (TTL) policies or event-driven invalidation helps maintain data freshness.
Batching Requests: Maximizing Throughput
Not every LLM API call needs to be handled individually. When multiple, independent requests can be processed together, request batching becomes a powerful optimization technique.
This is particularly effective for use cases where users might submit several similar, short prompts, or where background tasks can accumulate requests before sending them to the LLM.
Architecting for Batch Processing
We typically use message queues (e.g., RabbitMQ, SQS, Kafka) to collect individual requests. A dedicated worker service then polls these queues, aggregates a certain number of requests, and sends them as a single batched call to the LLM API.
The LLM response is then parsed, and individual results are routed back to their respective users or processes. This approach amortizes the overhead of network round trips and API call setup across multiple requests, leading to significant cost savings and often better throughput.
Asynchronous Processing: Keeping the UI Responsive
Direct, synchronous LLM API calls can block your application's main thread, leading to a sluggish user interface. Asynchronous processing decouches the request from the immediate response, improving perceived performance.
For tasks that don't require an instant answer, like generating long-form content or complex summaries, an asynchronous approach is essential. It ensures the user can continue interacting with your application while the AI processes their request in the background.
Designing Asynchronous Workflows
Our approach involves a clear separation of concerns. The front-end initiates a request, which immediately returns a 'processing' status. The backend then dispatches the LLM call to a separate worker process, often via a message queue.
Once the LLM response is received, the worker updates the database or triggers a notification (e.g., via websockets or server-sent events) to inform the user. This pattern significantly enhances the user experience by preventing UI freezes and offering real-time updates.
Monitoring and Alerting: The Unsung Hero
Optimizing LLM integrations isn't a 'set it and forget it' task. Continuous monitoring of API costs, latency, and error rates is non-negotiable for production systems.
Without robust observability, you won't know if your optimizations are working or if new bottlenecks are emerging. This can quickly lead to unexpected bills or frustrated users.
Implementing Comprehensive Observability
We integrate logging and metrics collection for every LLM API interaction. This includes tracking token usage, response times, and success/failure rates. Dashboards visualize these key performance indicators, providing immediate insights.
Automated alerts trigger when cost thresholds are exceeded, latency spikes, or error rates climb. This proactive approach allows us to address issues before they significantly impact users or budgets, aligning with our focus on reliable, scalable systems for clients.
Tradeoffs and Considerations
While these optimization strategies offer significant benefits, they also introduce architectural complexity. Caching requires careful invalidation logic. Batching adds queue management and potential delays for individual requests waiting to be grouped.
Asynchronous processing necessitates state management and notification systems. Each decision involves a tradeoff between performance, cost, and development effort. Our team carefully evaluates these factors to design solutions that fit specific product needs and budget constraints, as outlined in our foundational guide on Scaling AI SaaS: Architecting for High-Performance Inference and Data Pipelines.
The Business Value: Beyond Technical Metrics
The true value of LLM API integration optimization extends far beyond technical metrics. By reducing costs, Micro-SaaS businesses can offer more competitive pricing for AI features, making them accessible to a wider audience.
Improved latency directly translates to a smoother, more engaging user experience, which is critical for user retention and positive word-of-mouth. These engineering decisions directly impact the long-term viability and growth potential of an AI-powered product.
At Muhyo Tech, our API integration and website speed optimization services emphasize these architectural considerations from day one. We ensure that AI features are not just functional but also performant, cost-effective, and scalable. This approach helps founders confidently launch and grow their AI-driven offerings without being blindsided by operational overhead.