


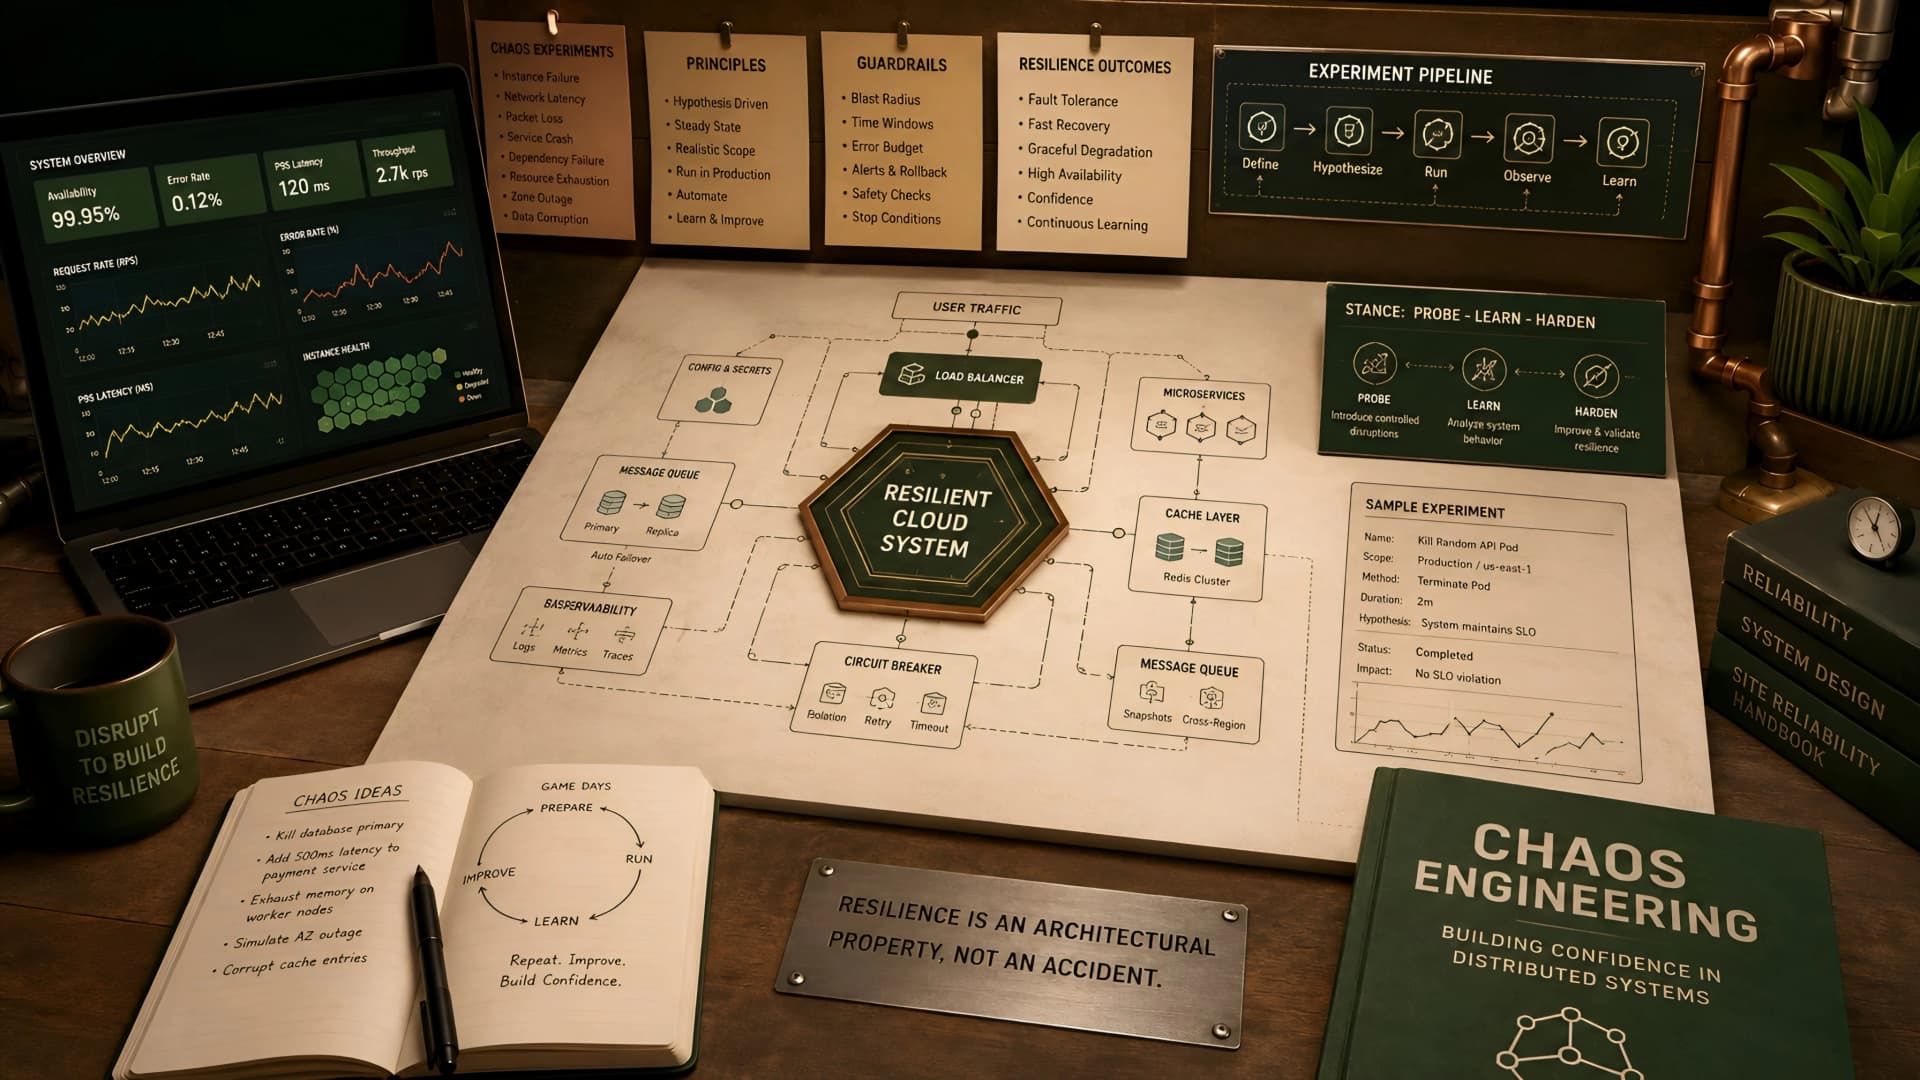
When we build complex cloud-native applications, we often aim for high availability and fault tolerance. Yet, the sheer scale and distributed nature of cloud infrastructure introduce a level of unpredictable complexity that traditional testing struggles to capture.
It's one thing to design for resilience on paper; it's another to see how your systems truly behave when a database connection drops, a network partition occurs, or a critical service experiences latency spikes. This is where Chaos Engineering steps in, transforming a reactive scramble into a proactive strategy.
The Unseen Cracks in Cloud Architectures
Every cloud system, no matter how well-architected, has hidden vulnerabilities. These weaknesses often emerge from unexpected interactions between services, subtle race conditions, or dependencies on third-party APIs that can fail without warning.
Relying solely on unit tests or integration tests provides a false sense of security. These tests validate expected behavior under ideal conditions, but production environments are rarely ideal.
Why Traditional Testing Falls Short for Cloud Resilience
Traditional testing methods, while essential, operate within a controlled scope. They verify specific functionalities or component interactions.
They struggle to simulate the cascading failures, resource contention, or network anomalies that define real-world cloud outages. This gap leaves critical blind spots in our understanding of system resilience.
What Exactly is Chaos Engineering?
Chaos Engineering is the discipline of experimenting on a system in order to build confidence in that system's capability to withstand turbulent conditions in production. Instead of waiting for failures to happen, we intentionally introduce controlled disruptions.
This scientific approach helps us discover weak points before they lead to customer-facing outages. It’s about learning from failure in a safe, controlled manner.
The Principles of Chaos Engineering
At Muhyo Tech, our approach to Chaos Engineering is guided by four core principles:
- Formulate a Hypothesis: Start by defining a steady state and hypothesizing how the system will behave under specific adverse conditions.
- Vary Real-World Events: Introduce a variety of realistic failure events, such as server crashes, network latency, or service dependency failures.
- Run Experiments in Production (Carefully): While initial experiments might occur in staging, the most valuable insights often come from production, albeit with extreme caution and safety measures.
- Automate Experiments: Manual chaos experiments are tedious and error-prone; automation ensures consistency and repeatability.
Setting Up Your First Chaos Experiment: A Practical Checklist
Before you inject any chaos into your system, preparation is key. A methodical approach minimizes risk and maximizes learning.
Here’s a practical checklist we often follow when guiding teams through their initial Chaos Engineering setups:
Pre-Experiment Checklist:
- Define a Clear Scope: What specific service or component are you testing? What's the blast radius?
- Identify Steady State Metrics: What does 'normal' look like? Define key performance indicators (KPIs) and service level objectives (SLOs) to monitor during the experiment.
- Establish a Rollback Plan: How will you stop the experiment immediately if things go wrong? This is non-negotiable.
- Notify Stakeholders: Inform relevant teams (DevOps, SRE, Product) about the planned experiment, its scope, and potential impact.
- Ensure Observability: Confirm that your monitoring, logging, and alerting systems are robust enough to detect anomalies caused by the experiment.
- Start Small and Iterate: Begin with minor, low-impact experiments in non-critical environments before escalating.
- Document Expected vs. Actual Outcomes: Record your hypothesis and compare it with the observed system behavior.
Common Chaos Engineering Scenarios in the Cloud
Chaos Engineering experiments can take many forms, depending on the specific weaknesses you're trying to expose. Here are a few common scenarios relevant to cloud systems:
1. Injecting Latency and Packet Loss
Problem: Many microservices assume perfect network conditions. Real-world networks are anything but.
Experiment: Introduce artificial network latency or packet loss between specific services or to external dependencies. Observe how your application handles slow responses or dropped connections, including retries, timeouts, and fallback mechanisms.
2. Resource Exhaustion
Problem: Services can become unstable or unresponsive under high CPU, memory, or disk I/O pressure.
Experiment: Simulate resource contention by temporarily maxing out CPU, memory, or disk on a critical instance. Evaluate if auto-scaling kicks in as expected and if other services degrade gracefully.
3. Service Dependency Failure
Problem: A single point of failure in a dependent service can cascade into a widespread outage.
Experiment: Gracefully shut down or degrade a critical dependency (e.g., a database replica, a caching service, or an authentication service). Verify that your application handles the failure with circuit breakers, fallbacks, or by degrading non-essential features.
4. Region or Availability Zone Outages
Problem: Cloud providers can experience localized outages, impacting an entire region or availability zone.
Experiment: Simulate the failure of an entire availability zone by isolating traffic or shutting down instances within it. This is a more advanced experiment, often done in staging, to confirm multi-AZ resilience and disaster recovery plans.
Key Tools for Cloud Chaos Engineering
The landscape of Chaos Engineering tools has matured significantly. Choosing the right tool depends on your cloud provider, system architecture, and desired level of control.
Here's a comparison of some popular options:
| Tool | Description | Key Features | Cloud Agnostic? | Complexity |
|---|---|---|---|---|
| Gremlin | SaaS platform for running a variety of chaos experiments. | Extensive attack library (CPU, memory, network, disk, shutdown); scheduling; API integration. | Yes | Low (Managed Service) |
| Chaos Mesh | Cloud-native Chaos Engineering platform for Kubernetes. | Fault injection for Pods, network, filesystem, kernel; CRD-based; supports Helm. | No (Kubernetes-specific) | Medium |
| LitmusChaos | Cloud-native Chaos Engineering framework for Kubernetes. | Open-source; large experiment library; GitOps-friendly; integrates with observability tools. | No (Kubernetes-specific) | Medium |
| AWS Fault Injection Simulator (FIS) | Managed service for performing fault injection experiments on AWS. | Specific to AWS services (EC2, ECS, EKS, RDS, etc.); templates for common scenarios. | No (AWS-specific) | Low (Managed Service) |
| Azure Chaos Studio | Managed service for performing chaos experiments on Azure. | Supports Azure VMs, AKS, App Services; built-in fault library; integrated with Azure Monitor. | No (Azure-specific) | Low (Managed Service) |
Integrating Chaos Engineering into Your DevOps Workflow
Chaos Engineering isn't a one-off project; it's an ongoing practice. To truly embed resilience, it needs to be integrated into your continuous delivery and operational workflows.
At Muhyo Tech, we often advise clients to automate small, controlled chaos experiments as part of their CI/CD pipeline, especially in staging environments. This ensures that new deployments are always tested for resilience against known failure modes.
Automating Chaos and Learning from Failures
Scheduled chaos experiments, perhaps weekly or monthly, help maintain vigilance. When an experiment uncovers a weakness, it should trigger an incident response and a post-mortem process.
The lessons learned should feed back into architectural improvements, code changes, and new resilience patterns, making the system stronger with each iteration. This continuous feedback loop is crucial for long-term reliability.
The Business Value of Embracing Chaos
While the idea of intentionally breaking things might seem counterintuitive to business leaders, the value proposition of Chaos Engineering is clear and compelling.
It translates directly into tangible business benefits, especially for applications where uptime and user trust are paramount.
Reduced Downtime and Enhanced User Experience
By proactively identifying and fixing vulnerabilities, you significantly reduce the likelihood of unexpected outages. This means more consistent service availability and a better experience for your users, leading to higher retention and satisfaction.
Improved Incident Response and Team Confidence
When failures are discovered through controlled experiments, your engineering teams get invaluable practice in incident response. They learn to diagnose problems faster, develop more robust runbooks, and build confidence in their ability to restore service quickly when real incidents occur.
Lower Maintenance Risk and Cost Savings
Preventing major outages is always less costly than reacting to them. Chaos Engineering helps you avoid the financial impact of lost revenue, reputational damage, and emergency engineering efforts. It also contributes to lower maintenance risk over the long term, as the system becomes inherently more stable.
Trade-offs and Considerations
Implementing Chaos Engineering isn't without its challenges. It requires a mature observability stack, a disciplined engineering culture, and a willingness to invest in tools and training.
There's always a perceived risk when introducing faults into a system, which is why starting small, having robust rollback plans, and communicating clearly are so vital. The benefits, however, generally outweigh these initial hurdles for critical applications.
Frequently Asked Questions
Q: What's the biggest risk when starting with Chaos Engineering?
The biggest risk is uncontrolled blast radius – an experiment impacting more than intended, leading to an actual outage. Mitigate this by starting with very small, isolated experiments, having clear rollback procedures, and ensuring robust monitoring.
Q: Can Chaos Engineering be applied to legacy systems not built for the cloud?
While most effective in cloud-native, microservices architectures, aspects of Chaos Engineering can be adapted to legacy systems. Focus on network failures, resource exhaustion, or dependency failures that can be isolated without rewriting the core application logic.
Q: How do I convince my leadership team to invest in Chaos Engineering?
Frame it as an investment in business continuity and risk reduction. Highlight the costs of downtime, the reputational damage of outages, and how proactive resilience building through Chaos Engineering reduces these risks. Emphasize improved incident response times and team confidence.
Q: How often should we run chaos experiments?
The frequency depends on your system's maturity and change velocity. For rapidly evolving systems, automated, small-scale experiments can run continuously in staging. Larger, more impactful experiments might be scheduled weekly or monthly, with dedicated 'Game Days' for more complex scenarios.
Building a More Resilient Future
In a world where cloud systems are the backbone of modern businesses, embracing Chaos Engineering is no longer a niche practice; it's a fundamental aspect of responsible engineering. It moves us beyond hoping for reliability to actively proving it.
By systematically breaking things in a controlled manner, we don't just fix immediate bugs; we cultivate a deeper understanding of our systems and build an engineering culture focused on true resilience. This proactive mindset is precisely how we approach robust system design and ongoing reliability for our clients at Muhyo Tech, ensuring their digital presence is not just functional, but truly antifragile.