


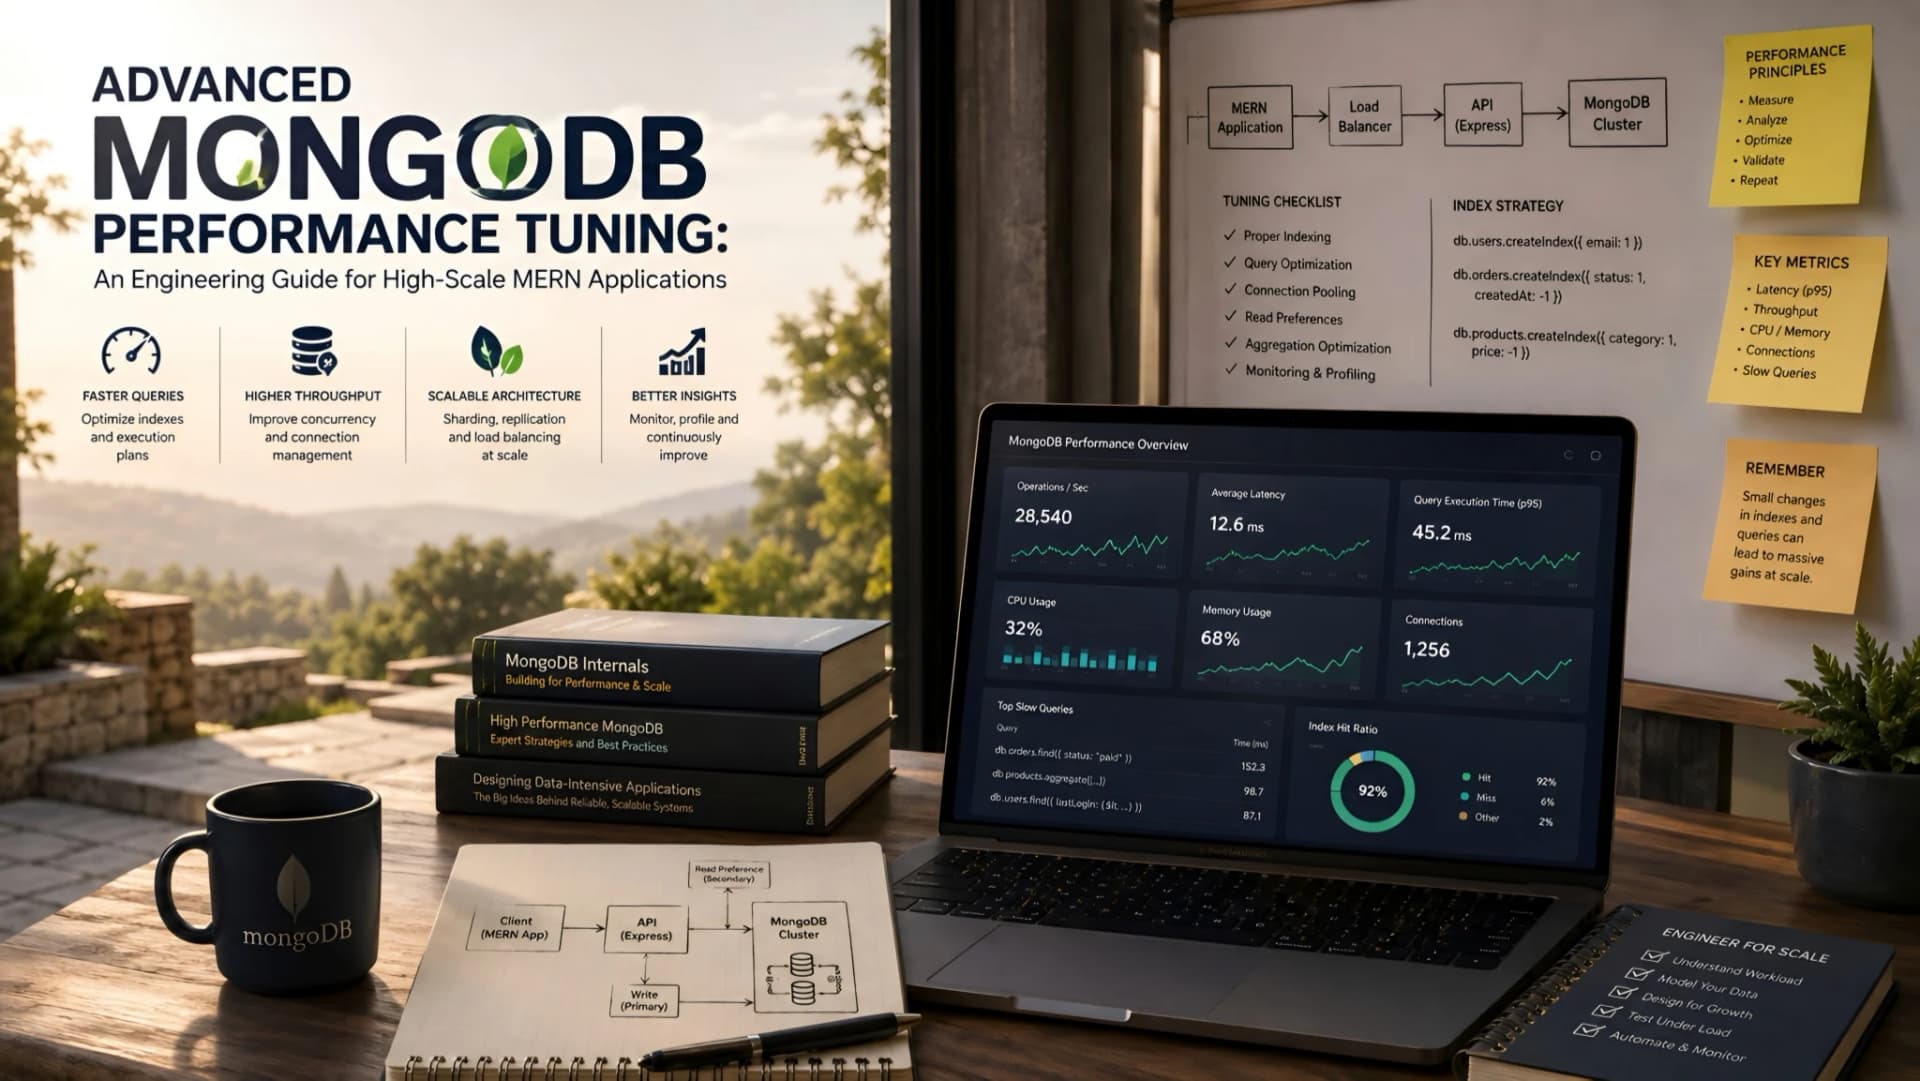
Advanced MongoDB Performance Tuning: An Engineering Guide for High-Scale MERN Applications
Building MERN applications is exciting, but scaling them brings a familiar challenge: database performance. A slow MongoDB database can cripple even the most well-designed frontend, leading to frustrated users and escalating infrastructure costs.
This isn't just about adding more RAM; it's about understanding the nuances of your data, queries, and MongoDB's architecture. At Muhyo Tech, we approach these challenges by diving deep into the data layer, ensuring the database supports the application's growth, not hinders it.
The Root Causes of MongoDB Performance Bottlenecks in MERN
Before we optimize, we need to diagnose. Many MERN performance issues stem from a few common culprits. Understanding these helps us target our engineering efforts effectively.
Inefficient queries are often the primary offender, especially when they scan entire collections. Poorly chosen or missing indexes force MongoDB to work harder than necessary, turning simple operations into expensive full-collection scans. This overhead quickly becomes unsustainable under load.
Suboptimal schema design also plays a significant role. MongoDB's flexibility can be a double-edged sword; an ill-considered schema, perhaps with overly large documents or deep nesting, can lead to frequent data movement and slow reads/writes. Document size and structure directly impact how efficiently data is stored and retrieved.
Strategic Indexing: The Foundation of Fast Queries
Indexes are to MongoDB what a table of contents is to a book: they allow the database to find data quickly without reading every page. Proper indexing is the single most impactful optimization for query performance.
We start by analyzing query patterns using MongoDB's profiler, identifying fields frequently used in find(), sort(), and aggregate() operations. Compound indexes, covering multiple fields, are often more effective than single-field indexes, especially for complex queries. However, too many indexes can slow down writes and consume excessive memory.
Types of Indexes and Their Use Cases
- Single-Field Indexes: Basic index on a single field. Ideal for simple equality matches.
- Compound Indexes: Index on multiple fields. The order of fields matters significantly for query efficiency.
- Multikey Indexes: Indexes fields that hold array values. Essential for querying data within arrays.
- Text Indexes: Supports text search queries on string content. Great for free-text search functionality.
- Geospatial Indexes: For efficient queries on geographical data, such as finding points within a certain radius.
- Hashed Indexes: Indexes the hash of a field's value. Useful for sharding but less common for query optimization.
Best Practices for Indexing in MERN Applications
Always create indexes in development, test their impact, and then deploy to production. Monitor index usage with db.collection.stats() and the profiler to identify unused indexes that can be dropped.
Consider partial indexes for collections with many documents where only a subset meets specific criteria. This reduces index size and write overhead. For example, indexing only active users in a large user collection.
At Muhyo Tech, we treat indexing as an iterative process. It's not a 'set it and forget it' task; as query patterns evolve, so too should our indexing strategy. We prioritize indexes that support the most critical and frequent read operations, balancing read speed with write performance.
Optimizing MongoDB Query Execution
Indexes are crucial, but even with perfect indexes, poorly written queries can still underperform. Understanding how MongoDB executes queries is key to writing efficient ones.
The explain() method is an indispensable tool here. It provides detailed information about query plans, including which indexes are used, the number of documents scanned, and the execution time. Analyzing the executionStats and winningPlan helps pinpoint bottlenecks.
Common Query Optimization Techniques
- Projection: Only retrieve the fields you need. Using
{ field: 1, _id: 0 }in your query significantly reduces network traffic and memory usage. - Sort and Limit: Combine
sort()andlimit()with appropriate indexes. If a query needs to sort a large dataset before limiting, the sort operation can be expensive without a covering index. - Aggregation Pipeline Optimization: Push filtering (
$match) and projection ($project) stages as early as possible in the pipeline. This reduces the amount of data processed by subsequent stages. - Avoid
$skipwith Large Offsets: For pagination,$skipbecomes very inefficient with large offsets. Consider using range queries with sort on an indexed field for better performance. - Use
$textWisely: Text searches can be resource-intensive. For complex full-text search, consider integrating with dedicated search engines like Elasticsearch.
Example: Optimizing an Aggregation Pipeline
Inefficient:
db.orders.aggregate([
  { $project: { customerName: '$customer.name', total: '$itemsTotal', date: 1 } },
  { $match: { date: { $gte: ISODate('2023-01-01') } } },
  { $group: { _id: '$customerName', totalOrders: { $sum: 1 }, totalRevenue: { $sum: '$total' } } }
]);
Optimized:
db.orders.aggregate([
  { $match: { date: { $gte: ISODate('2023-01-01') } } }, // Filter early
  { $project: { customerName: '$customer.name', total: '$itemsTotal' } }, // Project after filtering
  { $group: { _id: '$customerName', totalOrders: { $sum: 1 }, totalRevenue: { $sum: '$total' } } }
]);
By moving the $match stage earlier, we reduce the number of documents that need to be processed by subsequent stages, leading to a significant performance improvement. This is a core principle we apply when designing data retrieval for MERN applications.
Schema Design for Performance and Scalability
MongoDB's flexible schema is a powerful feature, but it demands careful consideration. The choice between embedding and referencing documents directly impacts query efficiency, data consistency, and application complexity.
Embedding related data within a single document can reduce the number of queries needed, making reads faster. However, large embedded documents can lead to performance issues if frequently updated, as MongoDB may need to relocate the entire document. Overly large documents also increase network overhead.
Embedding vs. Referencing: A Trade-off Analysis
| Feature | Embedding | Referencing |
|---|---|---|
| Read Performance | Generally faster (fewer queries) | Requires multiple queries (joins in application logic) |
| Write Performance | Slower if embedded documents grow significantly (document relocation) | Generally faster (smaller documents, less relocation) |
| Data Consistency | Stronger (single document update) | Requires transactional logic for multi-document updates |
| Data Duplication | Higher (if same data is embedded in multiple parent documents) | Lower (data stored once) |
| Query Complexity | Simpler for related data | More complex (requires application-level joins) |
| Scalability | Good for small, frequently accessed sub-documents | Better for large, frequently updated, or loosely coupled data |
Practical Schema Design Tips for MERN
- Keep Documents Lean: Avoid excessively large documents if parts of them are frequently updated.
- Pre-aggregate Data: For dashboards or analytics, pre-aggregate frequently requested summaries to reduce real-time computation.
- Use Covered Queries: Design queries and indexes so that all the data required by the query is available in the index itself. This means MongoDB doesn't need to fetch the actual documents from disk.
- Consider Atomic Updates: For frequently updated fields within an embedded document, use operators like
$inc,$set, and$pushto update only the specific field, avoiding full document rewrites.
Replica Sets and Sharding for High Availability and Scalability
As MERN applications grow, a single MongoDB instance becomes a bottleneck and a single point of failure. Replica sets and sharding are essential for production-grade scalability and resilience.
A replica set provides high availability by maintaining multiple copies of your data across different servers. If the primary node fails, an election occurs, and a new primary is automatically chosen, minimizing downtime. This is crucial for business continuity and uptime guarantees.
Replica Sets: Beyond Basic Redundancy
Replica sets also enable read scaling. You can direct read operations to secondary members, distributing the load and improving read throughput. This is particularly useful for analytical queries or reporting that can tolerate slightly stale data.
Configuring replica sets properly involves choosing the right number of members, understanding write concerns (e.g., w: 'majority'), and managing elections. We often recommend at least a three-member replica set for production environments to ensure robust fault tolerance.
Sharding: Horizontal Scaling for Massive Datasets
When a single replica set can no longer handle your data volume or write throughput, sharding becomes necessary. Sharding distributes data across multiple independent MongoDB instances (shards), each storing a portion of the data.
The key to successful sharding lies in choosing an effective shard key. A good shard key distributes data evenly across shards, preventing hot spots and allowing queries to target specific shards. A poor shard key can negate the benefits of sharding, leading to uneven data distribution and performance degradation.
Shard Key Considerations:
- Cardinality: The shard key should have a large number of unique values.
- Frequency: The frequency of values should be relatively even.
- Monotonicity: Avoid monotonically increasing or decreasing keys for even distribution (unless hashed sharding is used).
- Query Isolation: Choose a key that allows most queries to be routed to a single shard (targeted reads), minimizing scatter-gather operations.
Monitoring and Profiling: The Eyes and Ears of Performance
You can't optimize what you can't measure. Robust monitoring and profiling are indispensable for understanding MongoDB's behavior in production. This allows us to catch performance regressions early and proactively address issues.
MongoDB's built-in tools, like the database profiler and various diagnostic commands (db.serverStatus(), db.currentOp()), provide a wealth of information. Integrating with external monitoring solutions like Prometheus/Grafana or cloud-native monitoring services (e.g., AWS CloudWatch, Azure Monitor) provides a holistic view of your database health.
Key Metrics to Monitor
- Query Latency: Average time taken for queries. Spikes indicate bottlenecks.
- Index Usage: See which indexes are being used and how effectively.
- Page Faults: High page faults suggest data isn't fitting in RAM, leading to disk I/O.
- Connections: Monitor active connections to avoid exhaustion.
- Replication Lag: For replica sets, ensure secondaries are caught up with the primary.
- Opcounters: Track read, write, and command operations to understand workload patterns.
Common Mistakes and How to Avoid Them
Even experienced engineers can fall into common MongoDB performance traps. Recognizing these patterns helps us build more robust MERN applications from the outset.
- Over-indexing: While indexes are good, too many indexes slow down write operations and consume memory. Index only what's necessary.
- Ignoring
explain(): Running queries without understanding their execution plan is like driving blindfolded. Always useexplain()during development and diagnosis. - Using Default Write Concerns in Production: For critical operations, ensure appropriate write concerns (e.g.,
w: 'majority') for data durability, balancing performance with safety. - Large Document Updates: Frequent updates to large documents can lead to performance issues due to document relocation. Use atomic operators or redesign the schema.
- Lack of Monitoring: Without monitoring, performance issues only become apparent when users complain, leading to reactive instead of proactive problem-solving.
Building for Performance from the Start: Our Approach at Muhyo Tech
At Muhyo Tech, we integrate performance considerations into every stage of MERN application development. It's not an afterthought; it's a core architectural principle.
We begin with data modeling workshops, meticulously designing schemas that anticipate future query patterns and scaling needs. Our team emphasizes iterative development, continuously profiling and optimizing as the application evolves.
This proactive approach means our MERN applications are built on a solid, performant database foundation, reducing long-term maintenance risk and ensuring a smoother user experience. It's about delivering reliable and scalable systems, not just functional ones.
Frequently Asked Questions (FAQs)
How do I know if my MongoDB queries are performing poorly?
The best way is to use the explain() method on your queries to analyze their execution plan. Look for high totalDocsExamined relative to nReturned, indications of full collection scans, and long executionStats.executionTimeMillis. Also, monitor your database's overall query latency metrics.
Is it always better to embed documents in MongoDB for MERN apps?
Not always. Embedding is excellent for one-to-one or one-to-few relationships where data is frequently accessed together and doesn't grow excessively. For one-to-many or many-to-many relationships, or data that is frequently updated independently, referencing is often a better choice to maintain smaller documents and avoid performance penalties from document growth and relocation.
What's the most critical first step for optimizing a slow MERN app's MongoDB?
Focus on indexing. Analyze your most frequent and slowest queries using the database profiler and explain(). Then, create appropriate indexes for the fields used in find(), sort(), and aggregation stages. Proper indexing often yields the most significant immediate performance gains.
When should I consider sharding my MongoDB database?
Consider sharding when a single replica set can no longer handle your data volume or write throughput. This typically happens when your dataset exceeds the memory capacity of a single machine, or when your write operations become a bottleneck on the primary node, even with optimized queries and indexing.