


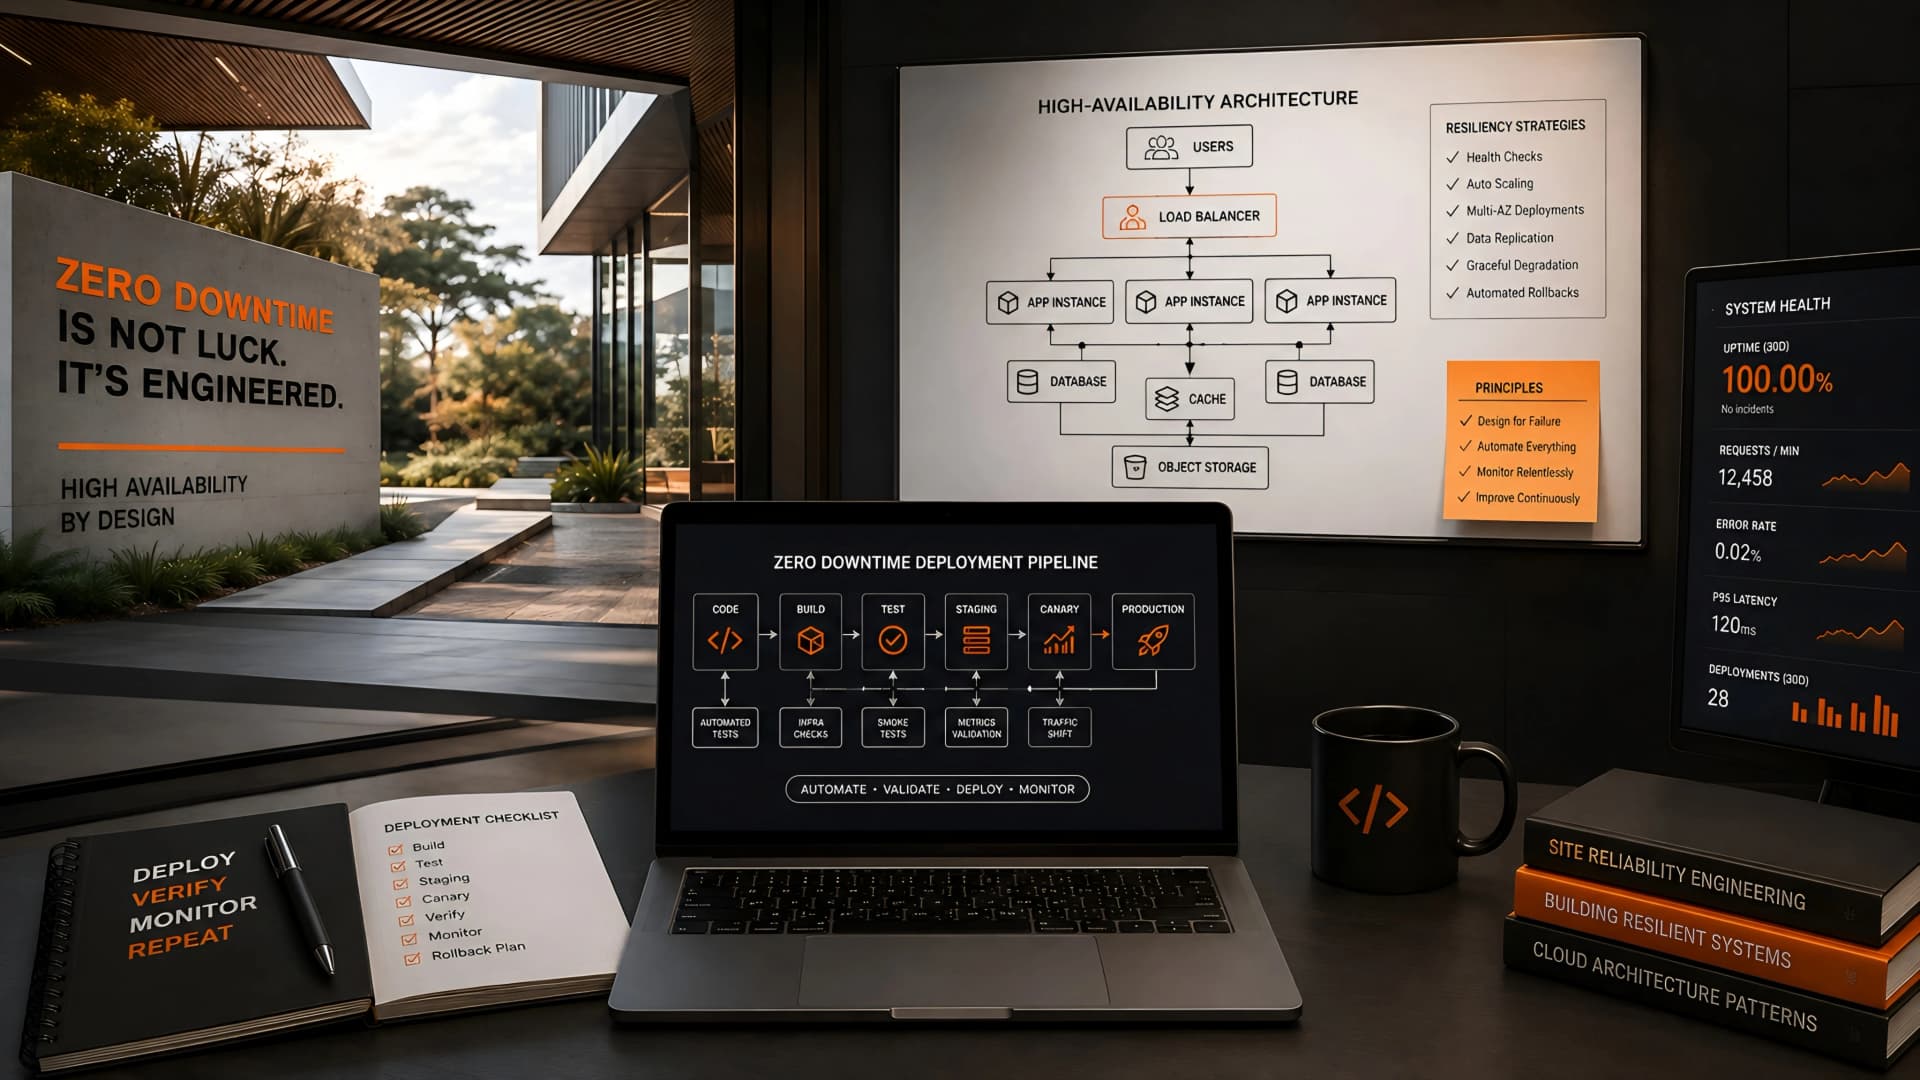
The pressure to innovate quickly in SaaS is constant. New features, bug fixes, and performance enhancements need to reach users fast.
However, every deployment carries a risk: potential downtime. Even a few minutes of service interruption can erode user trust, impact revenue, and damage brand reputation, especially for critical business applications.
Achieving zero downtime deployments is not just an aspiration; it's a fundamental requirement for high-availability SaaS products. It means delivering updates without users ever noticing a break in service.
This commitment to continuous availability defines a mature engineering practice. It's about building confidence in every release.
Understanding the Challenge of Downtime During Deployments
Traditional deployment methods often involve taking an application offline, updating the code, and then bringing it back up. This 'maintenance window' approach is unacceptable for modern SaaS.
Users expect 24/7 access, and any interruption, no matter how brief, can lead to frustration and churn. For B2B SaaS, downtime can directly translate to lost productivity for their customers.
Beyond direct service interruption, deployments can introduce subtle bugs that degrade performance or break specific features. Without careful staging and rollback capabilities, these issues can linger, causing prolonged negative experiences.
At Muhyo Tech, we consistently emphasize that robust deployment strategies are not an afterthought; they are integral to product reliability and user retention.
Pillars of Zero Downtime Deployment Strategies
Zero downtime deployments rely on a combination of architectural patterns, automation, and rigorous testing. The core idea is to introduce new versions of your application while keeping the old version running until the new one is fully validated.
This allows for seamless transitions and immediate rollbacks if issues arise. It requires careful planning across infrastructure, application code, and data management.
We break down these strategies into three primary patterns: Blue/Green Deployments, Canary Releases, and Rolling Updates.
Each method offers distinct advantages and suits different levels of risk tolerance and infrastructure complexity.
1. Blue/Green Deployments: The Parallel Environment Approach
Blue/Green deployments involve running two identical production environments, 'Blue' and 'Green'. At any given time, only one environment is actively serving user traffic.
When a new version is ready, it's deployed to the inactive environment (e.g., Green). Once deployed and thoroughly tested, traffic is switched from Blue to Green, typically by updating a load balancer or DNS record.
The old 'Blue' environment is kept as a live backup. If any issues emerge with the 'Green' deployment, traffic can be instantly switched back to 'Blue', achieving an extremely fast rollback.
This method offers high confidence in rollbacks and isolates new code changes. It's particularly effective for major version updates where significant changes might be present.
Pros of Blue/Green Deployments:
- Instant Rollback: The primary benefit is the ability to revert to the previous stable version almost instantly.
- Reduced Risk: New deployments are fully tested in a production-like environment before going live.
- Simplicity for Large Changes: Handles major architectural or dependency changes well.
Cons of Blue/Green Deployments:
- Resource Duplication: Requires double the infrastructure resources for a period, which can be costly.
- Database Migrations: Managing database schema changes can be complex, requiring forward and backward compatibility.
- State Management: Maintaining session state or other ephemeral data across environments needs careful design.
2. Canary Releases: Phased Rollouts for Risk Mitigation
Canary releases involve gradually rolling out a new version to a small subset of users before making it available to everyone. It's named after the 'canary in a coal mine' concept.
A small percentage of traffic is routed to the new version. Engineers monitor key metrics like error rates, latency, and user behavior.
If the new version performs as expected, the traffic share is slowly increased until 100% of users are on the new version. If problems arise, traffic is immediately routed back to the old version for the affected users.
This strategy is excellent for validating new features in a real-world production environment with minimal impact on the overall user base.
Pros of Canary Releases:
- Reduced Blast Radius: Limits the impact of potential bugs to a small group of users.
- Real-World Feedback: Allows for testing new features with actual user traffic.
- Gradual Rollout: Provides time to identify and fix issues before widespread impact.
Cons of Canary Releases:
- Complexity: Requires sophisticated traffic routing, monitoring, and analysis tools.
- Debugging: Identifying issues specific to the canary group can be challenging.
- Inconsistent User Experience: A small percentage of users might experience a different (and potentially buggy) version.
3. Rolling Updates: Gradual Instance Replacement
Rolling updates, also known as rolling deployments, involve incrementally replacing instances of the old application version with instances of the new version. This is common in containerized environments like Kubernetes.
A few old instances are shut down, and new instances with the updated code are spun up. This process continues until all old instances are replaced.
During the transition, both old and new versions of the application are running simultaneously, handling traffic. Load balancers distribute requests across available instances.
This method is resource-efficient as it doesn't require duplicating entire environments, making it a popular choice for microservices architectures.
Pros of Rolling Updates:
- Resource Efficiency: Does not require double the infrastructure, unlike Blue/Green.
- Simpler Implementation: Often easier to set up, especially with orchestration tools.
- Continuous Availability: Maintains service during the update process.
Cons of Rolling Updates:
- Slower Rollback: Reverting requires another rolling update, which can take time.
- Temporary Inconsistency: Both old and new versions serve traffic simultaneously, requiring backward compatibility in APIs and databases.
- State Management: Sessions and in-memory data need careful handling to avoid disruption.
Key Architectural and Operational Considerations for SaaS
Regardless of the chosen deployment strategy, several underlying principles and practices are essential for successful zero downtime deployments in a SaaS context.
These touch on everything from infrastructure design to application code and monitoring. Overlooking any of these can undermine even the most robust deployment plan.
Database Schema Migrations
Database changes are often the trickiest part of zero downtime deployments. A simple schema change can break an older version of the application.
We always advocate for a multi-stage approach to database migrations. This involves making changes backward-compatible first, deploying the application that can work with both schemas, and then, in a subsequent deployment, removing the old schema elements.
Using tools for schema versioning and transactional migrations is non-negotiable. It allows for safe evolution of your data layer.
API Versioning and Backward Compatibility
For microservices and APIs, maintaining backward compatibility is crucial. Newer versions of services must be able to interact with older versions of other services.
API versioning (e.g., /v1/users, /v2/users) allows you to introduce breaking changes without impacting existing clients or older service versions. Deprecate old APIs gracefully, providing ample time for clients to migrate.
This approach ensures that during a rolling update or a Blue/Green transition, different service versions can coexist and communicate effectively.
Robust Monitoring and Alerting
You can't achieve zero downtime if you don't know when something goes wrong. Comprehensive monitoring is the backbone of any advanced deployment strategy.
Monitor application performance metrics (latency, error rates, throughput), infrastructure health (CPU, memory, disk I/O), and user experience metrics. Set up actionable alerts for any deviation from baselines.
Observability tools that provide distributed tracing and detailed logging are invaluable for quickly pinpointing the root cause of issues in complex environments.
Automated Testing Pipelines
Every deployment pipeline must include extensive automated tests: unit, integration, end-to-end, and performance tests.
These tests act as your first line of defense, catching regressions and critical bugs before they reach production. The faster you can identify issues, the safer your deployments become.
At Muhyo Tech, our CI/CD pipelines are designed with this principle in mind, ensuring a high level of test coverage and automatic validation at every stage.
Configuration Management and Environment Parity
Inconsistencies between development, staging, and production environments are a common source of deployment failures. Use configuration management tools (e.g., Ansible, Terraform) to ensure environment parity.
Externalize configurations from your application code, using environment variables or dedicated configuration services. This allows you to deploy the same artifact across environments, only changing the configuration.
This practice significantly reduces the 'it worked on my machine' syndrome and makes deployments more predictable.
Comparison Matrix: Choosing the Right Strategy
Selecting the best zero downtime deployment strategy depends on your application's architecture, team's maturity, and specific business needs. Here's a quick comparison:
| Feature | Blue/Green | Canary Releases | Rolling Updates |
|---|---|---|---|
| Complexity | Medium | High | Low to Medium |
| Cost (Infrastructure) | High (Duplicate Environments) | Medium (Incremental) | Low (Incremental) |
| Rollback Speed | Instant | Fast (for affected users) | Moderate (requires another rollout) |
| Risk Mitigation | High (full testing before switch) | Highest (gradual exposure) | Medium (gradual replacement) |
| Database Migrations | Complex (requires dual compatibility) | Complex (requires dual compatibility) | Complex (requires dual compatibility) |
| Ideal Use Case | Major architectural changes, critical apps | New feature validation, high-risk changes | Frequent small updates, microservices |
The Muhyo Tech Approach to Deployment Reliability
At Muhyo Tech, our approach to zero downtime deployments is rooted in pragmatism and a deep understanding of production realities. We typically begin by assessing the client's current infrastructure and application architecture.
For many web applications and smaller SaaS products, we often start with robust rolling updates, augmented by comprehensive health checks and automated rollbacks. This provides a strong foundation without immediate over-engineering.
As complexity grows, especially with critical B2B SaaS platforms or microservice-heavy architectures, we layer in more sophisticated strategies like canary releases. We design for observability from day one, ensuring that every deployment is measurable and reversible.
Our goal is always to balance rapid iteration with unwavering stability. We integrate these practices into our full-stack web app development and maintenance and support offerings.
Common Pitfalls and How to Avoid Them
Even with the best intentions, zero downtime deployments can fail. Recognizing common pitfalls is the first step to avoiding them.
Ignoring Database Compatibility
This is arguably the most frequent cause of deployment failures. Deploying new code that expects a different database schema than the one currently running will inevitably lead to errors.
Solution: Always design database migrations for backward and forward compatibility. Use a 'expand and contract' pattern: first add new columns/tables, deploy new code, then remove old columns/tables in a subsequent deployment.
Lack of Comprehensive Monitoring
Deploying without adequate visibility is like driving blindfolded. You won't know if something is broken until users report it.
Solution: Implement robust application performance monitoring (APM), error tracking, and log aggregation. Set up automated alerts for key metrics and anomalies. Actively review dashboards during and after deployments.
Insufficient Automated Testing
Manual testing is slow and prone to human error. Relying solely on it will slow down your deployment cadence and increase risk.
Solution: Invest heavily in automated test suites: unit, integration, and end-to-end tests. Ensure your CI/CD pipeline enforces passing all critical tests before any deployment to production environments.
Poor Rollback Strategy
A deployment isn't truly zero downtime if you can't quickly and safely revert to a stable state when things go wrong.
Solution: Design for quick rollbacks. With Blue/Green, it's a simple traffic switch. With rolling updates, ensure your orchestration tool supports quick reversion to a previous image. Practice rollbacks regularly.
Building a Culture of Deployment Excellence
Technology alone isn't enough. Achieving zero downtime deployments also requires a cultural shift within engineering teams.
It means fostering a mindset of shared responsibility for reliability, continuous improvement, and a proactive approach to risk. Engineers need to feel empowered to stop a deployment if issues are detected.
Regular post-mortems for any production incident, regardless of severity, are crucial. These help identify systemic weaknesses and refine processes, leading to stronger, more resilient deployment practices over time.
This continuous feedback loop is what truly elevates an engineering organization's deployment capabilities.
Frequently Asked Questions
Q: What is the biggest challenge in implementing zero downtime deployments for SaaS?
A: The most significant challenge often lies in managing database schema changes and ensuring backward compatibility. Applications must be designed to work with both the old and new database schemas during a transition period, which requires careful planning and execution.
Q: How do I choose between Blue/Green, Canary, and Rolling Updates?
A: Your choice depends on factors like infrastructure cost tolerance, acceptable risk, and the nature of your application changes. Blue/Green offers instant rollback but costs more. Canary provides maximum risk mitigation through gradual rollout but adds complexity. Rolling updates are resource-efficient for frequent, smaller changes but have slower rollbacks.
Q: Can zero downtime deployments be achieved with legacy systems?
A: It's significantly more challenging with monolithic legacy systems not designed for modern deployment practices. It often requires substantial refactoring, introducing API layers, and potentially breaking the monolith into smaller services. While difficult, it's often a necessary step to improve agility and reliability.
Q: What role does automation play in zero downtime deployments?
A: Automation is absolutely critical. It ensures consistency, speed, and repeatability across the entire deployment pipeline, from testing and building to deployment and monitoring. Manual steps introduce human error and slow down the process, making true zero downtime virtually impossible to sustain.
Conclusion: The Business Value of Uninterrupted Service
Implementing zero downtime deployment strategies is more than just a technical exercise. It's a strategic investment that directly translates into significant business value.
It means happier users who never experience service interruptions, leading to higher retention and stronger brand loyalty. It enables faster innovation cycles, allowing your team to deliver new features and improvements without fear of disrupting service.
For SaaS companies, continuous availability is a competitive advantage. By embracing these advanced deployment strategies, you not only build a more resilient product but also solidify your reputation as a reliable and forward-thinking provider.
This commitment to operational excellence is a hallmark of scalable, successful SaaS engineering.